Causal comparative research studies groups that already differ in a trait or past event. The person running the study did not assign that trait or event. The question is what might explain a gap between the groups' results.
The word “causal” needs care. A higher score in one group does not, by itself, show what caused the gap. How the groups formed and what else differed matter.
This guide shows how to read those details and save a checked note. The tutoring packet is fictional. A short excerpt from a real paper shows how its groups were defined. Atlas can help read supplied sources, and you judge what they support.

Check the basis of a group comparison
Keep the group definitions, measures and other explanations together.
What causal comparative research compares
The groups start with a trait or event that was not assigned in the study. People might have taken a course, used a service or scored above a set point on a test before the work began.
The study asks how their results differ and why that might be. Del Siegle's methods guide places this work among designs that study links between variables. The groups are already formed.
You will also see ex post facto, meaning after the fact. Read the dates to see what that means in the paper. A study may follow a past event with a later test, or use only old records.
QuestionPro's guide warns that a link between two variables does not prove that one drives the other. Keep that limit beside the design name when reading a result.
This approach helps when you cannot assign the event of interest. It can show a group gap worth studying further. The work still needs sound tests, permission to use the records and clear limits on what the results mean.
Distinguish comparison from experimental assignment
Ask how the experience happened
In a randomized experiment, chance decides who receives the planned treatment. Siegle's group-design distinction contrasts that with groups already formed. Sorting people into groups for a study does not assign them that past event.
Troy's methods lesson uses the past event as a design marker. Read how the study was done before deciding from its title. Fields and course texts may use terms in different ways.
Separate sampling from assignment
Random sampling selects who enters the sample. Random assignment decides who gets a treatment. You could draw a sample of past tutoring users by chance, but that would not change how they chose to use the service.
Troy's lesson on experiments separates those tasks. One helps with who a sample can speak for. The other helps assess whether a treatment, rather than prior group differences, explains a result.
Correlational work studies links between measured variables. Here the focus is a stated gap between groups. The same data may be used for both tasks; neither name alone tells you whether the claimed cause is well supported.
If group membership starts with whether an outcome already occurred, check case-control versus cross-sectional sampling. That comparison asks why people entered the study. An existing group label alone cannot tell you whether selection was based on an outcome or a population sample.
Locate how each group was defined
Find the rule that puts a person or record in each group. “Users” could mean people who opened a service, finished one session or used it every week. Each rule would sort people in a different way.
Record the cutoff, date range and source behind that rule. Was it set before the results were known? Mind the Graph's group-selection guidance makes the basis for membership a key check. A vague label can hide a choice that changes what a reported gap means.
In Ucar, Bozkurt and Zawacki-Richter's original study, procrastination scores define low and high groups through a median split. The excerpt shows the stated score ranges.
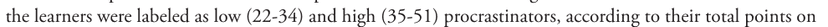
Ucar, Bozkurt and Zawacki-Richter, methods, journal page 16. Direct excerpt of the group-definition sentence.
The scores sort people by a trait that was measured. Nobody was assigned to procrastinate. Those cutoffs belong to this paper; they are not a rule for all students or a reason to split every score into two groups.
In their limitations section, the authors say they cannot be sure the proposed causes explain the outcome changes. Keep that limit with the group rule when writing about the paper.
Check the outcome and its timing
State what a score means before using it in a comparison. A final test, course grade and self-rating of learning each tell you something different. Even the same label can hide a change in scoring rules.
Check whether both groups took the same test in similar settings. A test watched by a teacher and one done at home may yield different scores for reasons beyond the trait you want to study.
Mind the Graph's guide discusses tests, rating scales and records as sources of data. Having them all does not make them equivalent. Read how each study obtained its scores and what they mean.
Put the dates in order: prior skill, the event of interest and the later test. A skill test taken after tutoring began cannot stand in for a test of skill before it began.
For a reading plan, write research objectives that name the groups and what you will check. “Compare final-test scores between stated user groups” keeps the task clear. It does not promise to isolate the service's effect.
A worked existing-group comparison
This packet is fictional teaching material, with no actual students, collected data or calculated results. It contains three made-up documents:
- A, methods page 2 and results page 4: A report compares students who used tutoring at least once during the term with students who did not. It reports higher final-test scores among users, using the same end-of-term test.
- B, baseline page 1: A record says no common pre-tutoring test was available. It contains no checked comparison of the groups' prior skill.
- C, access paragraph 3: A service note says tutoring sessions ran during weekday afternoons. It gives no group-specific account of timetable access or reasons for attendance.
Read the rows as links between a passage, a comparison decision and its limit. Replace the teaching locators with checked passages when working with real studies.
| Reading issue | Located support | What the packet supports | What remains open |
|---|---|---|---|
| Group membership | A methods p. 2 | At least one tutoring use versus none | Frequency, reasons for use and prior differences |
| Reported outcome | A results p. 4 | Higher final-test scores among users | Whether tutoring caused the difference |
| Prior skill | B baseline p. 1 | No common pre-tutoring test is available | Comparable starting skill is not established |
| Access | C paragraph 3 | Sessions ran on weekday afternoons | Whether access shaped who attended |
Table 1: The four rows retain the observed comparison while identifying the missing support for a causal interpretation.
Correct the causal sentence
“Tutoring improved students' test scores” goes beyond this packet. A checked version is: “The fictional report records higher final-test scores among users. It does not settle the role of prior skill or why students chose to attend.”
The new wording keeps the reported score gap and explains why its cause is not settled. Prior skill and access might matter, but the packet does not show that either caused the gap. Both need further checks.
Keep alternative explanations visible
Follow a plausible rival account
Students with stronger prior skills might seek help more often. Those with more free time might find it easier to attend. Both ideas are worth checking, but the made-up access note does not show that either happened.
A theoretical framework can explain why a rival account is worth testing. It links a proposed cause to prior reasoning and studies. That link gives you a reason to look; it does not show what happened in this packet.
Troy's group-comparison lesson asks what else might explain the result. Follow that question into the study's methods. A named gap that bears on its claim is more useful than a stock list of possible flaws.
Check what the study addressed
A confounding variable could explain both who joined a group and how they scored. That differs from a test problem, such as giving one group an easier test. Each concern needs its own check.
Igelstrom and colleagues' causal-inference glossary explains why design and assumptions matter. When a model adjusts for a trait, ask why that trait was chosen and what was not measured. The model's name does not answer those questions.
Matching students on prior scores could address one known gap. It would not make their choice to attend random or remove every other possible cause. Troy's matched-sample example shows why you should record which traits were matched and who was left out.
A missing record does not show that the groups started equal. This packet has no common test of earlier skill. Write “starting skill has not been established” so the next reader can see exactly what is missing.
Read the reported analysis in context
Preserve the comparison being estimated
Find what the study reports. A gap in mean scores answers a different question from the share of people with an outcome. A model may estimate another stated link. Keep the group rules and score scale beside each result.
Mind the Graph lists several ways to analyze data. Which fits depends on the question, the data and the assumptions. Read why the authors chose their test; there is no single test for all these studies.
Read beyond a significance label
Record the stated effect estimate and how precise it is, when the paper gives those details. A significance label alone cannot tell you how large or useful the gap is. It also cannot repair a missing earlier test or a concern about who joined each group.
If a paper reports both a simple comparison and one adjusted for other traits, keep both. State what the model took into account and what each result means. Igelstrom and colleagues' design glossary helps frame the assumptions behind that adjustment.
The made-up packet states only which group scored higher. It gives no effect size, interval or model details. Mark those as missing. A tool's knowledge of similar studies cannot supply this study's absent results.
Compare supplied studies in Atlas
Prepare the source set
Bring the studies, supplements and your reading criteria into one project, where you have permission to use them. Include the group rules and test details. Abstracts alone may miss those details, and sensitive records still need the access controls your work requires.
Select Add a source, then Upload files to import PDFs. Wait for processing and check that you can read the pages you need. Find a missing methods page or a clearer copy before relying on a claim drawn from it.
Inspect and save the interpretation
- In Ask a question, type @ and select the studies and criteria. Ask: “Compare how the groups formed, what was measured and when, what the study found and what else might explain it. Cite each row. Keep reported findings apart from possible causes, and mark missing details.”
- Open the numbered citations for each row. Check the source and surrounding passage. When an exact position is unavailable, locate the section manually; a relevant document alone does not support every claim in the answer.
- Revise claims that go beyond their sources and correct mismatched tests. For the fictional example, keep the higher-score result and the gaps about earlier skill and attendance. Taking the same final test does not show that groups started equal.
- Select New, then Note. Save the checked table, corrected conclusion, source locators and open questions. Give the note a useful title and wait for Saved before leaving it.
Atlas can help you read the supplied material side by side. It does not recruit people, run the paper's tests or certify what caused a result. You check each passage and judge what the design can support.
Save a conclusion the evidence supports
A useful note names the groups, result, source and limit together. Keep what the paper found, then explain how far that finding can take you. A sentence can lose a causal overclaim without losing the result that made the study worth reading.
Keep the table with your research notes, including source versions and open questions. A new supplement or reviewer comment may change a row. Record why it changed so the next reader can trace the earlier basis.
For the fictional packet, a new test of prior skill could answer one open question. It would need to concern the same groups and the right earlier period. The next source should address a named gap, so you can see what it adds.
Finish the reading task with source links for the group rules, tests, results and other possible causes. A stronger claim about cause and effect needs more support from the design and data. Confidence in the prose cannot supply that support.
Check the basis of a group comparison
Keep the group definitions, measures and other explanations together.